
Michael Limberger
Need me? Email mike@limberger.ca
AI
More features (the parts we did not demo)
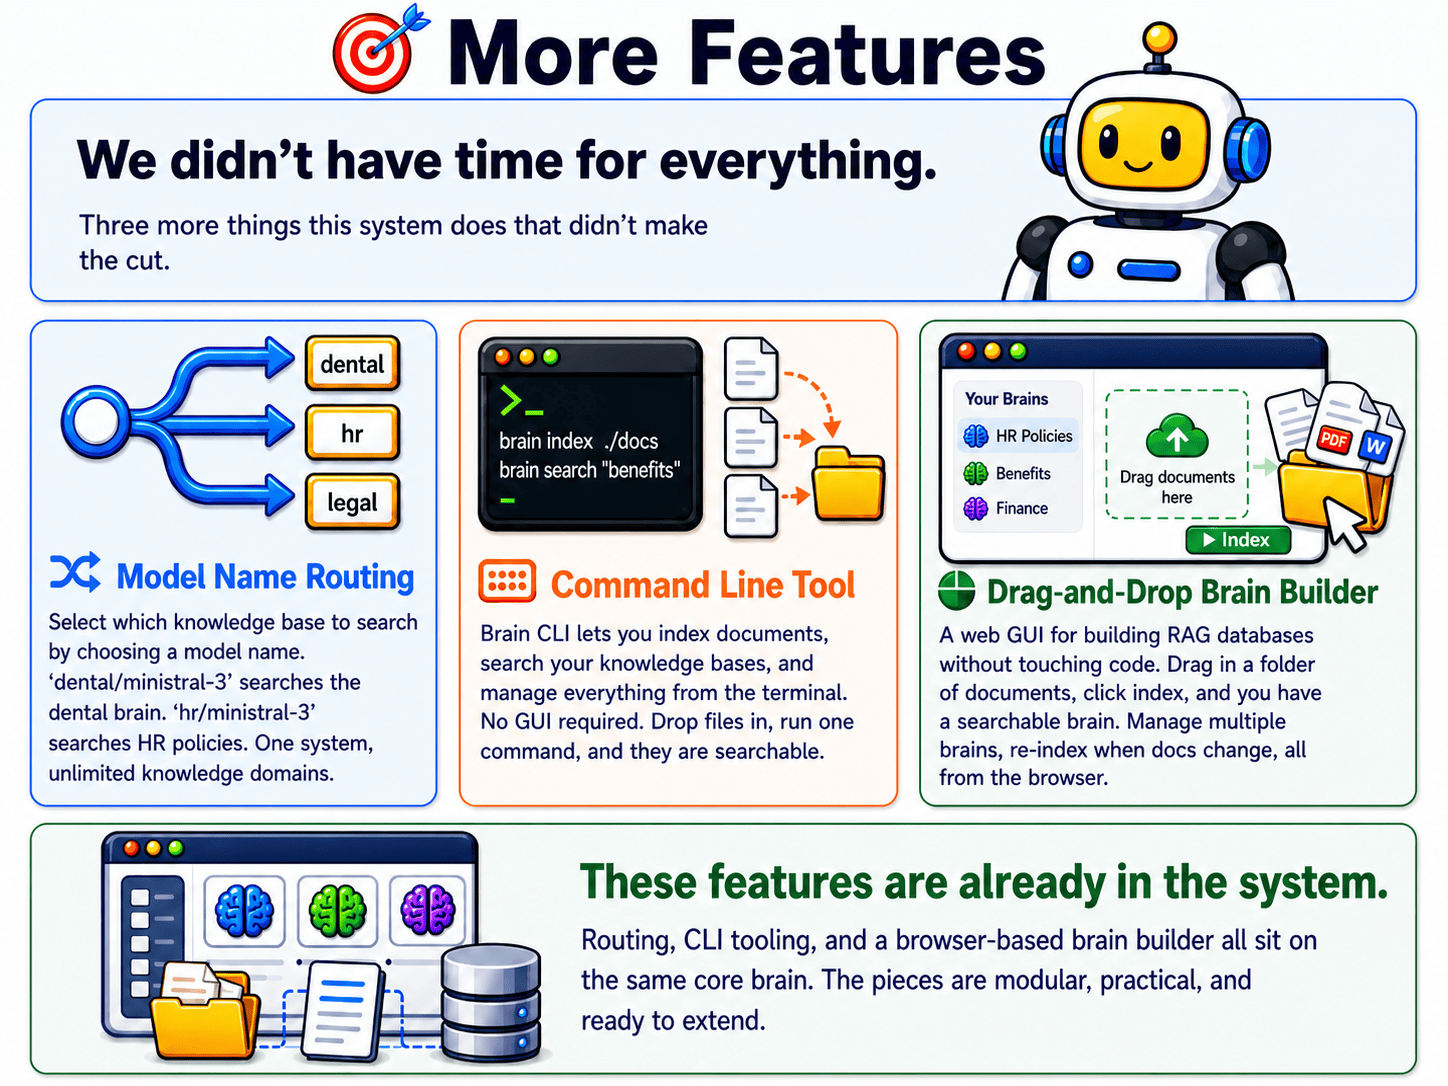
We did not demo every feature live. This page covers the extras that still matter once the basic retrieval path works.
Retrieval means we find the useful pages, put them in the prompt, and generate from that. That is what "modular" actually means here: three doors, one retrieval engine.
More than fits in one talk
This part covers the three capabilities we did not get to demo, each one a different angle on the same engine. The purpose is to signal depth: the system is a real tool, not a demo toy, without going down three more rabbit holes in the live session. Built and in the system. This is not a wishlist. It is a tour of what is already there.
Model name routing, again
Already introduced in
part 10. Quick
recap, because it bears repeating. Select which knowledge
base to search by choosing a model name.
dental/ministral-3 searches the dental brain.
hr/ministral-3 searches HR policies. One
system, unlimited knowledge domains, and the only control
surface is the model dropdown the user already knows.
The deeper point: the proxy can register any number of
brains through BRAIN_<NAME> environment
variables. The dental brain, a Perl brain, an HR brain,
each is just a directory with a SQLite file and a vector
matrix. Adding a domain is adding a folder, not writing
code.
That last sentence is the architectural difference between "extending a feature" and "extending infrastructure." Feature extension is code work. Infrastructure extension is data work.
Show me: the command line
ragproxy-ingest is the command-line interface
for managing brains. No GUI required, no special tooling,
just a Perl script you run from your terminal.
# Make a new brain
ragproxy-ingest create hr-policies

# Index documents into it
ragproxy-ingest add hr-policies ./docs/

# Test the search
ragproxy-ingest search hr-policies "leave policy"

# See all brains
ragproxy-ingest list

# Re-index after documents change
ragproxy-ingest rebuild hr-policies
Why this matters: it makes the whole system
scriptable.
Index documents from a cron job
(0 3 * * * ragproxy-ingest rebuild policies).
Rebuild a brain as part of a deploy script. Test retrieval
quality from the terminal. Evaluate against gold-standard
questions in CI.
This is the exact thing built-in RAG (part 8) cannot do, because built-in RAG has no reachable surface. The CLI is what "RAG as infrastructure" looks like in practice. You can drive the system from any tool that can invoke a subprocess: Bash, Python, Perl, Make, GitHub Actions, anything.
Drift detection
A small but powerful pattern. Every night, a cron job re-indexes the policy documents. If the chunk count or token count changes significantly compared to yesterday, it sends an alert. That tells you somebody edited a document and the system has noticed.
You cannot build that from inside a chat app's hidden RAG.
You can build it in twenty lines of shell on top of
ragproxy-ingest.
The drag-and-drop brain builder
A web GUI for building knowledge bases without touching code. Drag in a folder of documents, click index, and you have a searchable brain. Manage multiple brains, re-index when documents change, all from the browser.
This is the on-ramp for non-technical users. Not everyone wants to live in a terminal. The CLI is for the scripters. The brain builder is for everyone else. Same core engine underneath, two front doors.
From the brain builder you can create a new brain (just a name), drop in files (drag-and-drop or click-to-upload), watch indexing progress, see chunk counts per document, trigger re-indexing, delete documents or whole brains, and run a test search to verify retrieval quality.
For an organization with non-developers who need to maintain their own knowledge bases, this is the difference between "a system the IT team has to babysit" and "a system the actual subject-matter experts can run."
Which one should you start with? If you script, the CLI. If you do not, the brain builder. Either way you end up with the same brains, usable by the proxy through model-name routing.
Could the brain builder be a SaaS one day? It could, but the design assumption is local. Multi-tenant brain builders introduce auth, isolation, and resource management that the current design intentionally does not have. That is a different product.
Three doors, one engine
Routing, the CLI, and the brain builder are not three separate products. They all sit on the same core, Brain.pm. Each one is just a different way to reach the same engine.
The retrieval engine has no idea whether it was called by the proxy, the command line, or the web builder. It just retrieves.
New front ends can be added without touching the core. The core can be improved without touching the front ends. That separation is not aspirational. It is how the code is actually shaped.
Front ends you could add tomorrow: a Slack bot that answers from your knowledge base when @-mentioned. A GitHub action that re-indexes documentation on every push. An API endpoint that other internal apps can hit. A VS Code extension that lets developers ask questions about codebase docs. None of those would require changing Brain.pm. They would each be a thin wrapper.
The proxy already exposes a direct API. Hit
/v1/chat/completions (OpenAI style) or
/api/chat (Ollama style) with curl or any HTTP
client. The retrieval happens regardless of who calls.
Say this plainly: this is why moving RAG out of the app mattered. Once retrieval is its own piece, you can wrap it in as many interfaces as you need. A feature locked in an app gets one interface, forever.
The pattern
Identify the core capability (retrieval). Build it as a self-contained piece (Brain.pm). Wrap it in whatever interfaces the use cases need (proxy, CLI, GUI). Add new interfaces as needed without touching the core.
The cost of getting this right early is small: extra discipline about boundaries. The cost of getting it wrong is enormous: the core capability is entangled with one interface and you spend years trying to extract it.
Three front ends, one engine
That separation is what "RAG as infrastructure" gets you that "RAG as a feature" can never give.