
Michael Limberger
Need me? Email mike@limberger.ca
AI
Wiring the proxy in, one config change
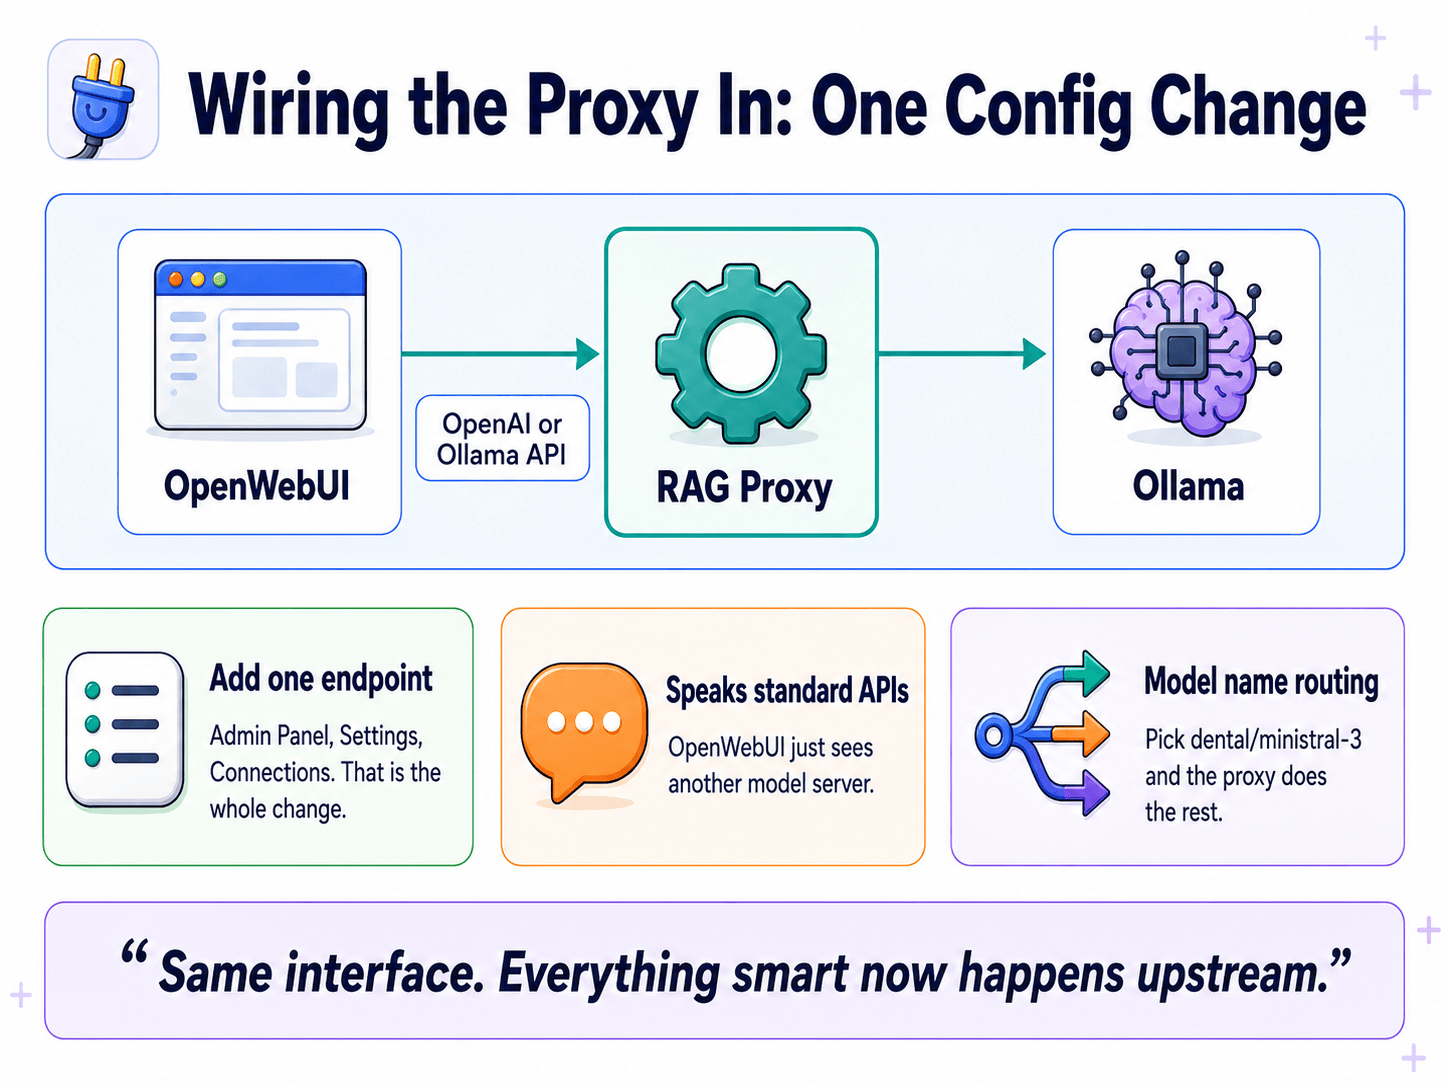
Wiring the proxy in is mostly configuration. Point the chat UI at the proxy instead of the model server, then let the proxy talk to the model. One hop in the middle.
Pick a model name like dental/ministral-3 and
the prefix tells the proxy which knowledge base to search.
Retrieval means we find the useful pages, put them in the prompt, and generate from that. The prefix is which pile of pages.
It does not require a rebuild
The proxy concept from the previous part sounds like it should require rebuilding your whole setup. It does not. You add one connection in OpenWebUI's settings and you are done.
The reason this works: the proxy speaks the two protocols every local AI client already knows. OpenWebUI already talks both. So from OpenWebUI's point of view, the proxy is just another model server. You change a URL. Nothing else.
Show me: OpenAI-compatible endpoint
- Admin Panel → Settings → Connections → OpenAI API → Add Connection
- URL:
http://your-proxy-host:PORT/v1(the proxy defaults to port 7079, sohttp://localhost:7079/v1) - API Key: anything non-empty if the proxy is not checking auth.
not-neededworks. - Save
Show me: Ollama-compatible endpoint
- Admin Panel → Settings → Connections → Ollama API → Add Connection
- URL:
http://your-proxy-host:PORT(no/v1on the Ollama path) - Save
Either way, that is the whole integration. Send a chat and the request now flows:
OpenWebUI → proxy → retrieval → Ollama → answerThe response flows back the other direction. The user sees a normal chat.
The model name is the routing instruction
This is the detail worth slowing down on, because it is how one proxy serves many knowledge bases. Whatever name the proxy advertises shows up in OpenWebUI's model dropdown. Pick a name, and the name tells the proxy what to do.
| Model name picked | What the proxy does |
|---|---|
ministral-3:14b |
No prefix, no brain. Pure passthrough, no RAG. |
dental/ministral-3:14b |
Prefix dental → search the dental brain, then forward to ministral-3. |
perl-ops/qwen3:8b |
Prefix perl-ops → search the perl brain and the ops brain, forward to qwen3. |
So the user picks dental/ministral-3 from a
normal dropdown. Behind the scenes the proxy reads that
prefix, searches the right document set, injects the
context, and routes to the right model. One system,
unlimited knowledge domains, and the only control surface is
the model selector the user already knows.
This is what "everything smart now happens upstream" means in practice. The chat app stays dumb and familiar. The intelligence moved one hop back, into the proxy. Adding a new knowledge domain is now a question of "create a brain" not "build a new UI."
The control surface already exists
A more naive design would invent a new widget. A knowledge base picker in the chat app. A second dropdown next to the model selector. A right-click menu. A keyboard shortcut. Each of those is more code, more documentation, and more learning curve.
The model-name-as-routing trick avoids all of it. Users already pick a model. We just make the name do double duty: model selection and knowledge selection in a single click. That kind of layering, finding the existing affordance instead of inventing a new one, is the design move that separates "infrastructure people use" from "infrastructure that lives in a wiki."
Gotchas worth knowing
If the proxy does not implement the model-list endpoint properly, OpenWebUI's "verify connection" button may error. Not fatal. Type the model name into the allowlist manually and it works. The proxy does implement the endpoint, so this is mainly a concern if you write your own version.
If two connected servers (proxy plus a direct Ollama, say) both expose a model with the same name, set a prefix on the connection to disambiguate. OpenWebUI allows this and it solves the conflict without renaming anything.
OpenWebUI runs background calls against the model: chat title generation, autocomplete suggestions, follow-up suggestions. The proxy detects and skips RAG on those (the code looks for title-generation patterns and passes them straight through). Otherwise those background calls would waste retrieval cycles on requests where retrieval is meaningless.
What you have after the proxy
Before: one chat app, one knowledge base, glued together. No way to reuse the knowledge from another tool. The chat app's defaults rule.
After: any number of knowledge bases, picked from a dropdown. The knowledge is reusable from any OpenAI- or Ollama-compatible client (curl, a Python script, another chat app, a Slack bot). The proxy's defaults rule, and you wrote them.
The work to integrate is the same in both cases (one configuration). The unlock is enormous. Do you have to change anything in OpenWebUI besides the connection? No. That is the headline.
How does the proxy speak both protocols at once? It
implements both sets of endpoints. The OpenAI-style paths
(/v1/models, /v1/chat/completions)
and the Ollama-style paths (/api/tags,
/api/chat). The client picks whichever it
prefers. The proxy answers in kind.
What if you want a knowledge base the proxy does not know
about yet? Register it as a new brain (one environment
variable, BRAIN_<NAME>), index your
documents into it, and it immediately becomes available as
a model-name prefix. No proxy code changes.
Does this work with chat apps other than OpenWebUI? Yes. Anything that speaks the OpenAI or Ollama protocol can talk to the proxy. CLI tools, curl scripts, custom apps, even other chat UIs. The proxy is interface-agnostic by design. Could you run multiple proxies? Sure. Different proxies on different ports, each serving different brains or different access levels. They are just servers. Compose them however you need.
Familiar shapes, new powers underneath
One connection in settings. One model-name prefix at chat time. That is the entire user-facing interface for "switch to a different knowledge base."