
Michael Limberger
Need me? Email mike@limberger.ca
AI
The research backed up the failures
The research matched what we saw in practice. Models fail in predictable ways when they do not have the source text. This page summarizes those failure modes without the jargon pile-on.
I went and read the papers
After five months of fine-tuning failures, I opened the literature. Turns out I was not the first. The pattern was documented. The numbers were public. The model creators themselves were quietly recommending exactly what I had been refusing to consider.
Three findings, each independent, each pointing the same direction.
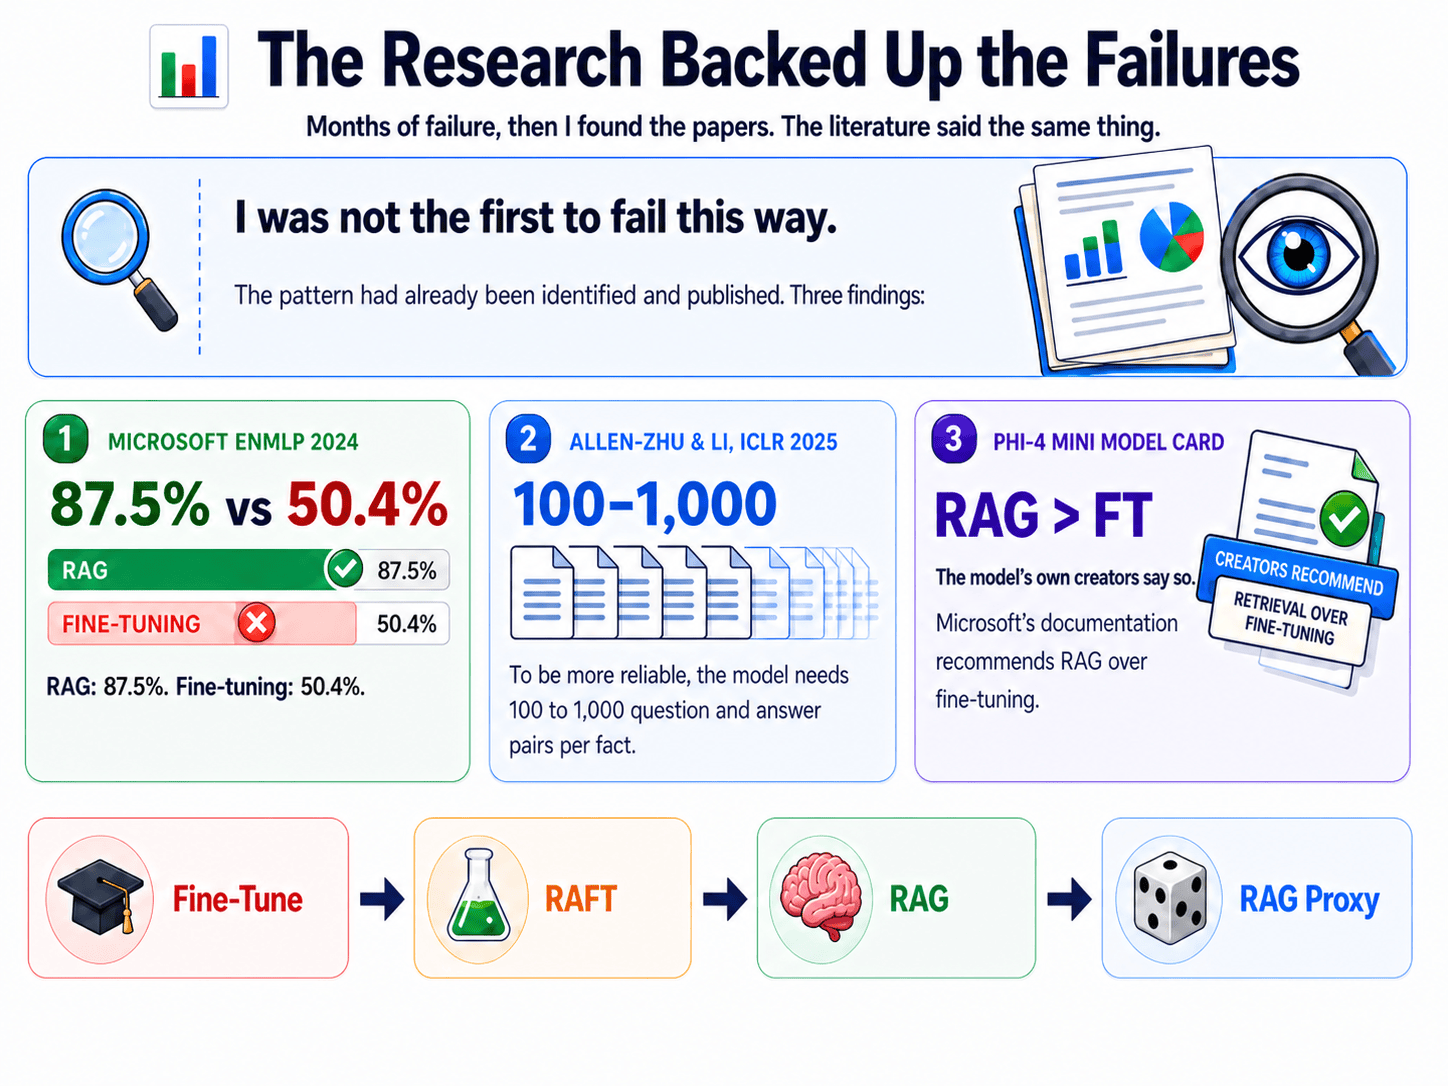
Microsoft, EMNLP 2024: 87.5% against 50.4%
Microsoft ran a controlled comparison. Same questions, same domain, same evaluation. RAG scored 87.5% accuracy. Fine-tuning scored 50.4%.
The plain-English read: fine-tuning for fact recall is barely better than a coin flip. RAG nearly doubles it.
This is not a small margin you can tune away with better hyperparameters (the knobs on a training run). It is a structural gap. Two completely different approaches. One works for knowledge tasks. One does not. The size of the gap is the size of "different category of solution."
The paper is published at EMNLP (Empirical Methods in Natural Language Processing) 2024. It is not a preprint, not a blog post, not a single team's anecdote. It went through peer review at one of the top NLP conferences.
Allen-Zhu and Li, ICLR 2025: 100 to 1,000 exposures
This study explains why the gap exists. For a language model to reliably learn a single fact through training, it needs to see that fact between 100 and 1,000 times, in varied contexts. Not 100 to 1,000 times across the whole corpus. That many times for each individual fact.
Now do the math on real documents. The Faculty's policy documents mention any given fact (an email address, a form number, a specific procedure) maybe 15 times across the whole corpus. That is off by two orders of magnitude from what training needs.
The training never had a chance. It is not a tuning problem. It is an arithmetic problem. You cannot fine-tune your way around a number that small.
The paper is published at ICLR 2025 (International Conference on Learning Representations). The researchers built synthetic datasets where they could control exactly how many times each fact appeared, then measured when the model would reliably recall it. The 100 to 1,000 range is the empirical threshold.
Phi-4 Mini's own card says use RAG
The most quietly damning finding. Phi-4 Mini is a small, capable model from Microsoft. When you download a model, it comes with a model card: the official note on what the model is good for, what it is not, and how to use it well.
Phi-4 Mini's model card recommends RAG over fine-tuning for knowledge tasks. When the people who built it, trained it, and know what it can and cannot do tell you not to fine-tune for facts, take that seriously. There is no clever configuration the creators missed. The advice is in the manual.
Two more that strengthen the case
The talk focuses on three findings. Two more sit behind them. Stanford's FineTuneBench showed a 37% generalization ceiling regardless of method or model size. Even fine-tuning done perfectly hits a wall. Scale does not save you.
Meta's LIMA paper introduced the Superficial Alignment Hypothesis: the formal claim that fine-tuning teaches format and tone, not new knowledge. That is the lived experience from part 3, stated as research.
Five independent sources, one conclusion.
The arrow at the bottom of the slide
The journey goes Fine-Tune, then RAFT, then RAG, then RAG Proxy. That is the arc of the whole talk.
| Stage | Plain English |
|---|---|
| Fine-Tune | The first attempt. Teaches style, not facts. Failed. |
| RAFT | Retrieval-Augmented Fine-Tuning. Works, but it needs a retrieval step alongside it. If retrieval is doing the work, why train at all. |
| RAG | Retrieval-Augmented Generation. Hand the model the documents at question time. The pivot that worked. |
| RAG Proxy | My build. RAG as a piece of infrastructure instead of a feature locked in one app. |
Every part after this one sits somewhere on that path.
Why these papers matter if you do not normally read papers
If someone in your organization pushes back on "we cannot fine-tune our way out of this," these are your receipts. Independent groups: Microsoft, two academics at ICLR, Stanford, Meta. Different methods. Same finding.
It is not your team that failed. It is not your data. It is the technique. The technique was the wrong tool for the job, and the literature said so before you started.
The frustrating part: the papers were available the whole time. The lesson I took out of this: check the literature before you spend five months on something. The problem you are working on has probably already been characterized.
Are these papers cherry-picked? They come from independent groups using different methods: controlled benchmarks, synthetic corpora, model-creator documentation, generalization studies. They point the same direction. That is the opposite of cherry-picking.
If you have already started a fine-tuning project, should you stop? Depends on what you are fine-tuning for. Style, format, voice, output structure: keep going. That is what fine-tuning is for. Facts and recall: the literature says you are going to hit a wall. RAG is the pivot.
Put knowledge in a layer
Five independent research groups, one conclusion: fine-tuning teaches style, not facts. Stop trying to put knowledge in the model. Put it in a layer.