
Michael Limberger
Need me? Email mike@limberger.ca
AI
Why use local AI?
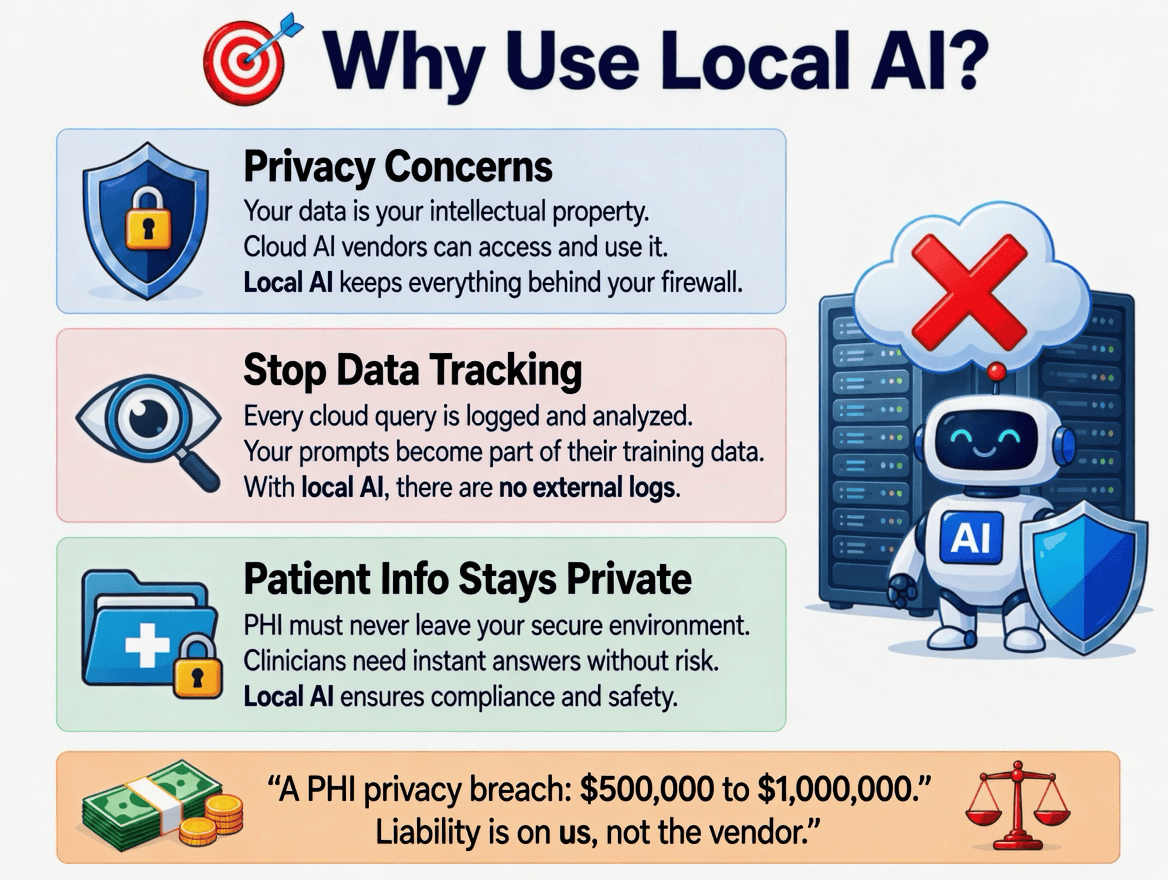
Why bother running AI on your own machines? Privacy, cost control, and the simple fact that some documents should not leave the building. This page walks through that case in plain language.
Why not just use ChatGPT?
Someone in the room is already thinking it. ChatGPT is better than anything you can run at home. For a casual question, fine. For drafting a policy, asking about a patient scenario, or working through internal infrastructure, the calculus changes.
Local AI is not always the right answer. It is the right answer when the data matters.
Your data is yours
When you send a prompt to a cloud AI (ChatGPT, Claude, Gemini, take your pick), that text leaves your building and lands on someone else's server. The vendor's policies are usually reasonable. They are also subject to change at any time, and they cannot retroactively unsend what you already sent.
For a casual "explain this regex" question, none of that matters. For a draft of an unpublished policy, a patient scenario rephrased to remove names, internal notes that describe how your network is segmented, you have just handed your intellectual property to a third party. There is no undo.
Local AI keeps every prompt and every document behind your firewall. The model runs on hardware you own. Nothing is transmitted. The privacy property is not a promise from a vendor. It is a property of the architecture.
Every cloud query is logged
This is not a conspiracy claim. It is in the terms of service. Cloud vendors log queries. Those logs can be analyzed, retained, and in many cases used to improve the vendor's future models. Your prompts can become training data for somebody else's product.
Some vendors offer "do not train on my data" toggles. Some offer enterprise tiers with stricter retention. All of those are policies on top of a system that, by design, does see your data. Removing the cloud removes the data-handling problem entirely.
With a local setup there are no external logs because there is no external anything. The only record is whatever you choose to keep on your own disk.
PHI cannot leave the building
This is the one that decides things for healthcare. In Ontario, PHI is governed by PHIPA (Personal Health Information Protection Act) and FIPPA (Freedom of Information and Protection of Privacy Act).
Patient-adjacent data cannot be sent to a cloud service. Not "should not." Cannot. Cloud AI was never an option for clinical use at the Faculty of Dentistry. Other places have their own fences: HIPAA in the US, GDPR in Europe. Same principle. Certain categories of data are legally fenced.
The cost of getting this wrong
A PHI privacy breach is often cited in the half-million to million-dollar range. That is the number to keep in mind the next time someone proposes piping clinic text through ChatGPT after stripping the names.
The reframe: local AI is not a fun privacy project. It is risk management. If a cloud AI leaks one patient record, the liability is on us, not the vendor. The vendor's terms of service make sure of that.
But anonymization?
The natural objection: just strip the names before sending. Two problems.
First, anonymization is hard to do perfectly. Names are obvious. Other identifiers (rare diagnoses, unusual procedure dates, distinctive case details) can re-identify a patient even with names removed. Studies have shown re-identification from "anonymized" data sets going back decades.
Second, getting it wrong once is the whole liability. The error budget is zero. You cannot fail to anonymize if you never sent it.
Outside healthcare
The PHI angle is healthcare-specific. The other two, intellectual property and tracking, apply to anyone with documents they would not paste into a public website. Internal architecture diagrams, unreleased product specs, draft contracts, financial models, anything under client confidentiality or an NDA. The threshold for "should this run locally" is lower than people assume.
Is local as good as the cloud?
Not as raw-capable, no. GPT-4 and Claude Opus are bigger than anything you can run at home. The later demo shows that for a focused job, read this passage and answer the question, a local model plus good retrieval gets you what you need. The capability gap matters less when the job is "read this and answer," not "write me a novel."
Is running models locally expensive? Less than people think. A used Mac Studio or a workstation GPU runs the models we use here. The recurring cost is zero. The PHI breach you avoided is between half a million and a million dollars. The math gets generous quickly.
Local was not a preference
It was a requirement. The data rules made the decision before any technical comparison was possible.